
 Infos für
 Direkt zu
 Fakultäten


Ringvorlesung: Computational Social Science
Wie lassen sich gesellschaftliche Entwicklungen mit digitalen Daten untersuchen? Welche Erkenntnisse kann die Informatik über politische Prozesse, soziale Ungleichheit oder gesellschaftlichen Wandel liefern?
Im Wintersemester 2026/27 lädt die Ringvorlesung Computational Social Science dazu ein, ein neues spannendes Forschungsfeld kennenzulernen. Computational Social Science ist eine neue Disziplin an der Schnittstelle zwischen Sozialwissenschaften und Informatik.
Die Vorlesungsreihe vermittelt einen grundlegenden Einblick in zentrale Konzepte, Datenquellen und analytische Verfahren der computergestützten Sozialforschung. Anhand konkreter Beispiele wird veranschaulicht, wie digitale Daten und moderne Analysemethoden dazu beitragen können, komplexe gesellschaftliche Herausforderungen besser zu verstehen. Jede Veranstaltung widmet sich einer gesellschaftlich relevanten Fragestellung und zeigt, wie computergestützte Methoden eingesetzt werden, um diese wissenschaftlich zu untersuchen.
Die Vorlesung findet auf Englisch statt.
Teilnahme und Registrierung: Teilnahme ist kostenlos. Es wird kein Vorwissen in Computational Social Science vorausgesetzt. Teilnehmende dürfen sowohl einzelne Terminen als auch die gesamte Vorlesungsreihe besuchen. Registrierung wird vorausgesetzt. Bitte kontaktieren Sie martin.ulrich(at)uni-saarland.de
An wen richtet sich diese Ringvorlesung?
- Alle Studierende der Universität des Saarlandes (LSF-Nummer 166580)
- Alle, die sich für Computational Social Science interessieren (Gasthörer:innen)
- Wissenschaftler:innen aus allen Fachrichtungen mit Interesse an interdisziplinärer Zusammenarbeit
Wer sind die Vortragenden? Forschende von …
- SOUNDS
- Interdisciplinary Institute of Societal Computing (I2SC)
- Max-Planck-Institut für Software Systems
- GESIS Leibniz-Institut für Sozialwissenschaften
- Andere deutsche und internationale Universitäten
Themenübersicht
This session introduces students and guest listeners to the contents of the lecture series. Main questions are: What is Computational Social Science? What is the SOUNDS project? How will the lecture series proceed?
Vortragender: Dr. Martin Ulrich (SOUNDS)
This session presents novel data sources that can be used for Social Sciences thanks to its collaboration with informatics. These novel data sources range from social media advertising data to satellite imagery.
Vortragende: Prof. Daniela Braun (Universität des Saarlandes, I2SC & SOUNDS) & Prof. Ingmar Weber (Universität des Saarlandes, I2SC, SOUNDS)
This session is the result of a cooperation between SOUNDS and AICS.
Crisis, such as conflict and extreme weather events that significantly impact populations, can exacerbate existing societal inequalities, and make it challenging to provide humanitarian aid. By improving how such crises are anticipated, vulnerable communities can be supported in strengthening mitigation measures and humanitarian aid resources can be prepositioned for more efficient and effective responses. This talk will discuss how taking a complex systems approach to model and simulate crises can help decision-makers understand crises more holistically, how heterogeneous populations area affected, and how the impacts of crises compound over time.
Vortragender: Dr. Joseph Aylett-Bullock (University of Bristol)
Over the past years, parallel developments have been shaping, or shaking, public opinion research: political crises demand rapid insight into fast-shifting attitudes, while recruiting participants for high-quality surveys is becoming slower and costlier. At the same time, the proliferation of generative AI has opened up new possibilities for social simulations. As a result, so-called “silicon samples” – data not collected from humans, but generated by AI based on existing human data, have become a research focus of computational social science. In this talk, I will provide an overview of the potentials and pitfalls of this approach. After a short introduction of the logic behind silicon samples and their relevance for political polling applications, I will draw on a systematic review as well as own applications in election prediction to showcase key challenges in modelling human attitudes and behaviors with AI, concerning both cross-sectional and longitudinal aspects. Presenting the Total Simulated Survey Error (TS2E) Framework as well as ongoing work, I will explain why errors might occur and how we can evaluate the quality of silicon public opinion data. I will close with the many aspects that remain to be explored when it comes to the design, evaluation, and ethics of silicon samples, and where computer science and political science can work together to answer them.
Vortragende: Dr. Leah von der Heyde (GESIS Leibniz-Institut für Sozialwissenschaften)
The rapid rise of Generative AI has enabled high-quality content creation across modalities, but such content is not always factually grounded. Large language models (LLMs), in particular, can produce false or misleading information—commonly known as hallucinations—due to limitations in training and inference. Beyond unintentional errors, these technologies can also be weaponized to fabricate and manipulate information at scale, amplifying disinformation across platforms and media. In this talk, I will examine how LLMs hallucinate, both organically and through adversarial manipulation, and discuss why existing AI safeguards remain insufficient to prevent AI-generated falsehoods. Against this backdrop, I will introduce “Humble AI”—AI systems that recognize limits in their knowledge and capabilities, hesitate when warranted, and choose productive alternatives such as verification, clarification, delegation, or abstention rather than proceeding despite insufficient evidence. The talk will conclude with broader societal implications and the need for proactive safeguards against AI-enabled harms.
Presenter: Prof. Dongwon Lee (Pennsylvania State University)
Vortragende: Prof. Zoë Greene (University of Strathclyde, Glasgow)
The continuous refinement of automated classification models offers many possibilities to content analysis in political science. But an important question remains, particularly in the context of long-standing human coding projects: Can and should computers truly substitute human coders, and how comparable are the results? Thus, instead of aiming for substitution this talk proposes combining automated and human coding to leverage the strengths of both approaches while circumventing their weaknesses. Two methods of human-machine cooperation are examined: divided coding and assisted coding. Both approaches combine human coders with a shared XML-RoBERTa model. On the example of the long-established Manifesto Project the talk explores to what extent such approaches can secure overtime comparability. The approaches are evaluated in terms of time savings, ease of coding and reliability. The results are encouraging, indicating that such cooperation can lead to significant time savings without substantially compromising reliability.
Vortragende: Dr. Pola Lehmann (Wissenschaftszentrum Berlin für Sozialforschung, WZB)
Prediction markets have emerged as a powerful source of real-time information about expectations of future events. In this lecture, we will first introduce the foundations of prediction markets, explain how they work, and discuss why they have become an increasingly valuable data source for computational social science and machine learning. We will then present our ongoing research on modeling the evolving state of the world using prediction market time series, including methods for identifying latent relationships between events, detecting market-wide anomalies, and uncovering potentially causal dependencies across interconnected markets. Finally, we will discuss how large language models can be used to characterize news and media sources by their influence on future market predictions, providing new perspectives on information diffusion, forecasting, and the interaction between media, human expectations, and AI. Overall, the lecture will highlight how prediction markets provide a unique setting for studying collective intelligence, forecasting, and AI, while outlining several open research challenges at the intersection of computational social science, economics, and machine learning.
Vortragende: Prof. Krishna Gummadi (Max-Planck-Institut for Software Systems), Prof. Marius Kloft (Rheinland-Pfälzische Technische Universität Kaiserslautern-Landau), Dr. Johnnatan Messias (Max-Planck-Institut for Software Systems)
This session is the result of a cooperation between SOUNDS and AICS.
Digital technologies and large-scale data are transforming urban governance - so promises the smart city. GIS-based planning tools and open data platforms suggest that cities are becoming ever more data-driven. Yet the everyday reality of urban planners tells a more ambivalent story. Drawing on qualitative workplace interviews with planners in small and medium-sized cities in Germany, Austria and Switzerland, this lecture presents research on how digital transformation is actually embedded - and obstructed - in planning practice. We show that planners navigate between innovative ambitions and erratic everyday routines: ICTs become meaningful only when anchored in local knowledge practices, while limited resources, hierarchical procedures and incomplete digitisation produce persistent frictions. In a second step, we ask what Computational Social Science can contribute to understanding urban planning and governance. We discuss the potential of text-based methods (e.g. analysis of planning documents, public consultation records, or social media debates about urban development), spatial data approaches (GIS, remote sensing, urban mobility data), and participatory data sources for studying planning processes at scale - and reflect on where computational approaches reach their limits and where qualitative, practice-oriented research remains indispensable.
Vortragende: Jun.-Prof. Carola Fricke (Universität des Saarlandes)
tba
Vortragende: Brahmani Nutakki (Universität des Saarlandes, I2SC)
Given the growing popularity of generative AI, including for voting advice, we pose the question: How reliable is ChatGPT as a source of political information? We collected ChatGPT’s responses about the positions of the main German parties prior to the 2025 federal election. Although ChatGPT correctly places each party in the expected left-liberal or right-conservative positions on average, its responses are also noisy and biased, making it a less reliable source of voting advice than more traditional sources. Our research therefore raises important questions for developers and regulators when considering the use of AI for sensitive topics.
Vortragender: Dr. Alex Hartland (Universität des Saarlandes)
Google Maps is used by billions of people every day — but beyond navigation, it holds a rich trove of data about how cities look, how businesses thrive or disappear, and how people experience public space. In this session, we explore how Google Maps data (street view imagery, place reviews, Points of Interest, and more) can serve as a novel data source for computational social science research. We discuss the unique advantages and limitations of this data, show how it can be combined with other datasets, and present concrete research examples that use it.
Vortragende: Ethel Elikem Afi Mensah (Universität des Saarlandes, I2SC)
Large language models (LLMs) are increasingly deployed as intelligent decision support systems for information processing tasks such as truthfulness and credibility assessment of information for different downstream tasks. Especially for high-risk use cases compliance with the EU AI Act is relevant, because errors, biases, or manipulation can affect public discourse and democratic processes. This talk asks whether transparency delivers the control it promises, or whether it creates an illusion of it. I argue that explanations can give a false sense of understanding and oversight, and that transparency requirements fall short unless they are tied to measurable improvements in human decision quality. I support this with findings from our research group on human-AI collaboration. First, LLMs are not neutral judges: biases and framing effects, including political leaning, systematically shape how they assess the truthfulness of information. Second, the explanations these systems give for their judgments do not necessarily reflect how the judgments were made, and their quality can degrade when models are compressed for efficient deployment. Third, explanations may increase people's trust in a system without improving the decisions they make with it. I then turn to an open question that needs input from outside computer science. In ongoing work with partners including DFKI and Aleph Alpha, we aim to align language models with a European value system. But who defines such a system, and how would we know that alignment has actually been achieved? I discuss how interpretability methods can help verify alignment rather than merely assume it, and where the limits of such verification lie. The talk closes with implications for researchers, regulators, and practitioners, and invites discussion on how social science and humanities perspectives can help define what "meaningful human oversight" should mean.
Vortragende: Prof. Vera Schmitt (Johannes-Gutenberg Universität Mainz)
Digital platforms have become central arenas of public life, where societal challenges (from climate change and migration to inequality and public health) are debated and shaped. To examine discourses, dynamics, and impacts across multilingual, multi-context digital publics, social scientists increasingly rely on AI-driven computational methods. This talk introduces methodological innovations in digital methods, focusing on computational multilingual text analysis and the problem of measurement validity. It present a validation framework that accounts for context-specific biases in automated measurement and demonstrate how it improves the robustness and comparability of findings across languages and platforms. In the second part, it showcases empirical studies that deploy the some of the tools to analyze public discourse around environmental and inequality-related policies, highlighting what AI can, and cannot, capture about actors, topics, and diffusion dynamics. The talk close with implications for research design, and the responsible use of AI in social science research.
Vortragende: Dr. Fabienne Lind
An diesem Termin findet die Klausur für die Studierenden der Vorlesung statt.
Wann und wo findet die Ringvorlesung statt?
Wann? Freitags, 12:15 - 13:45 Uhr
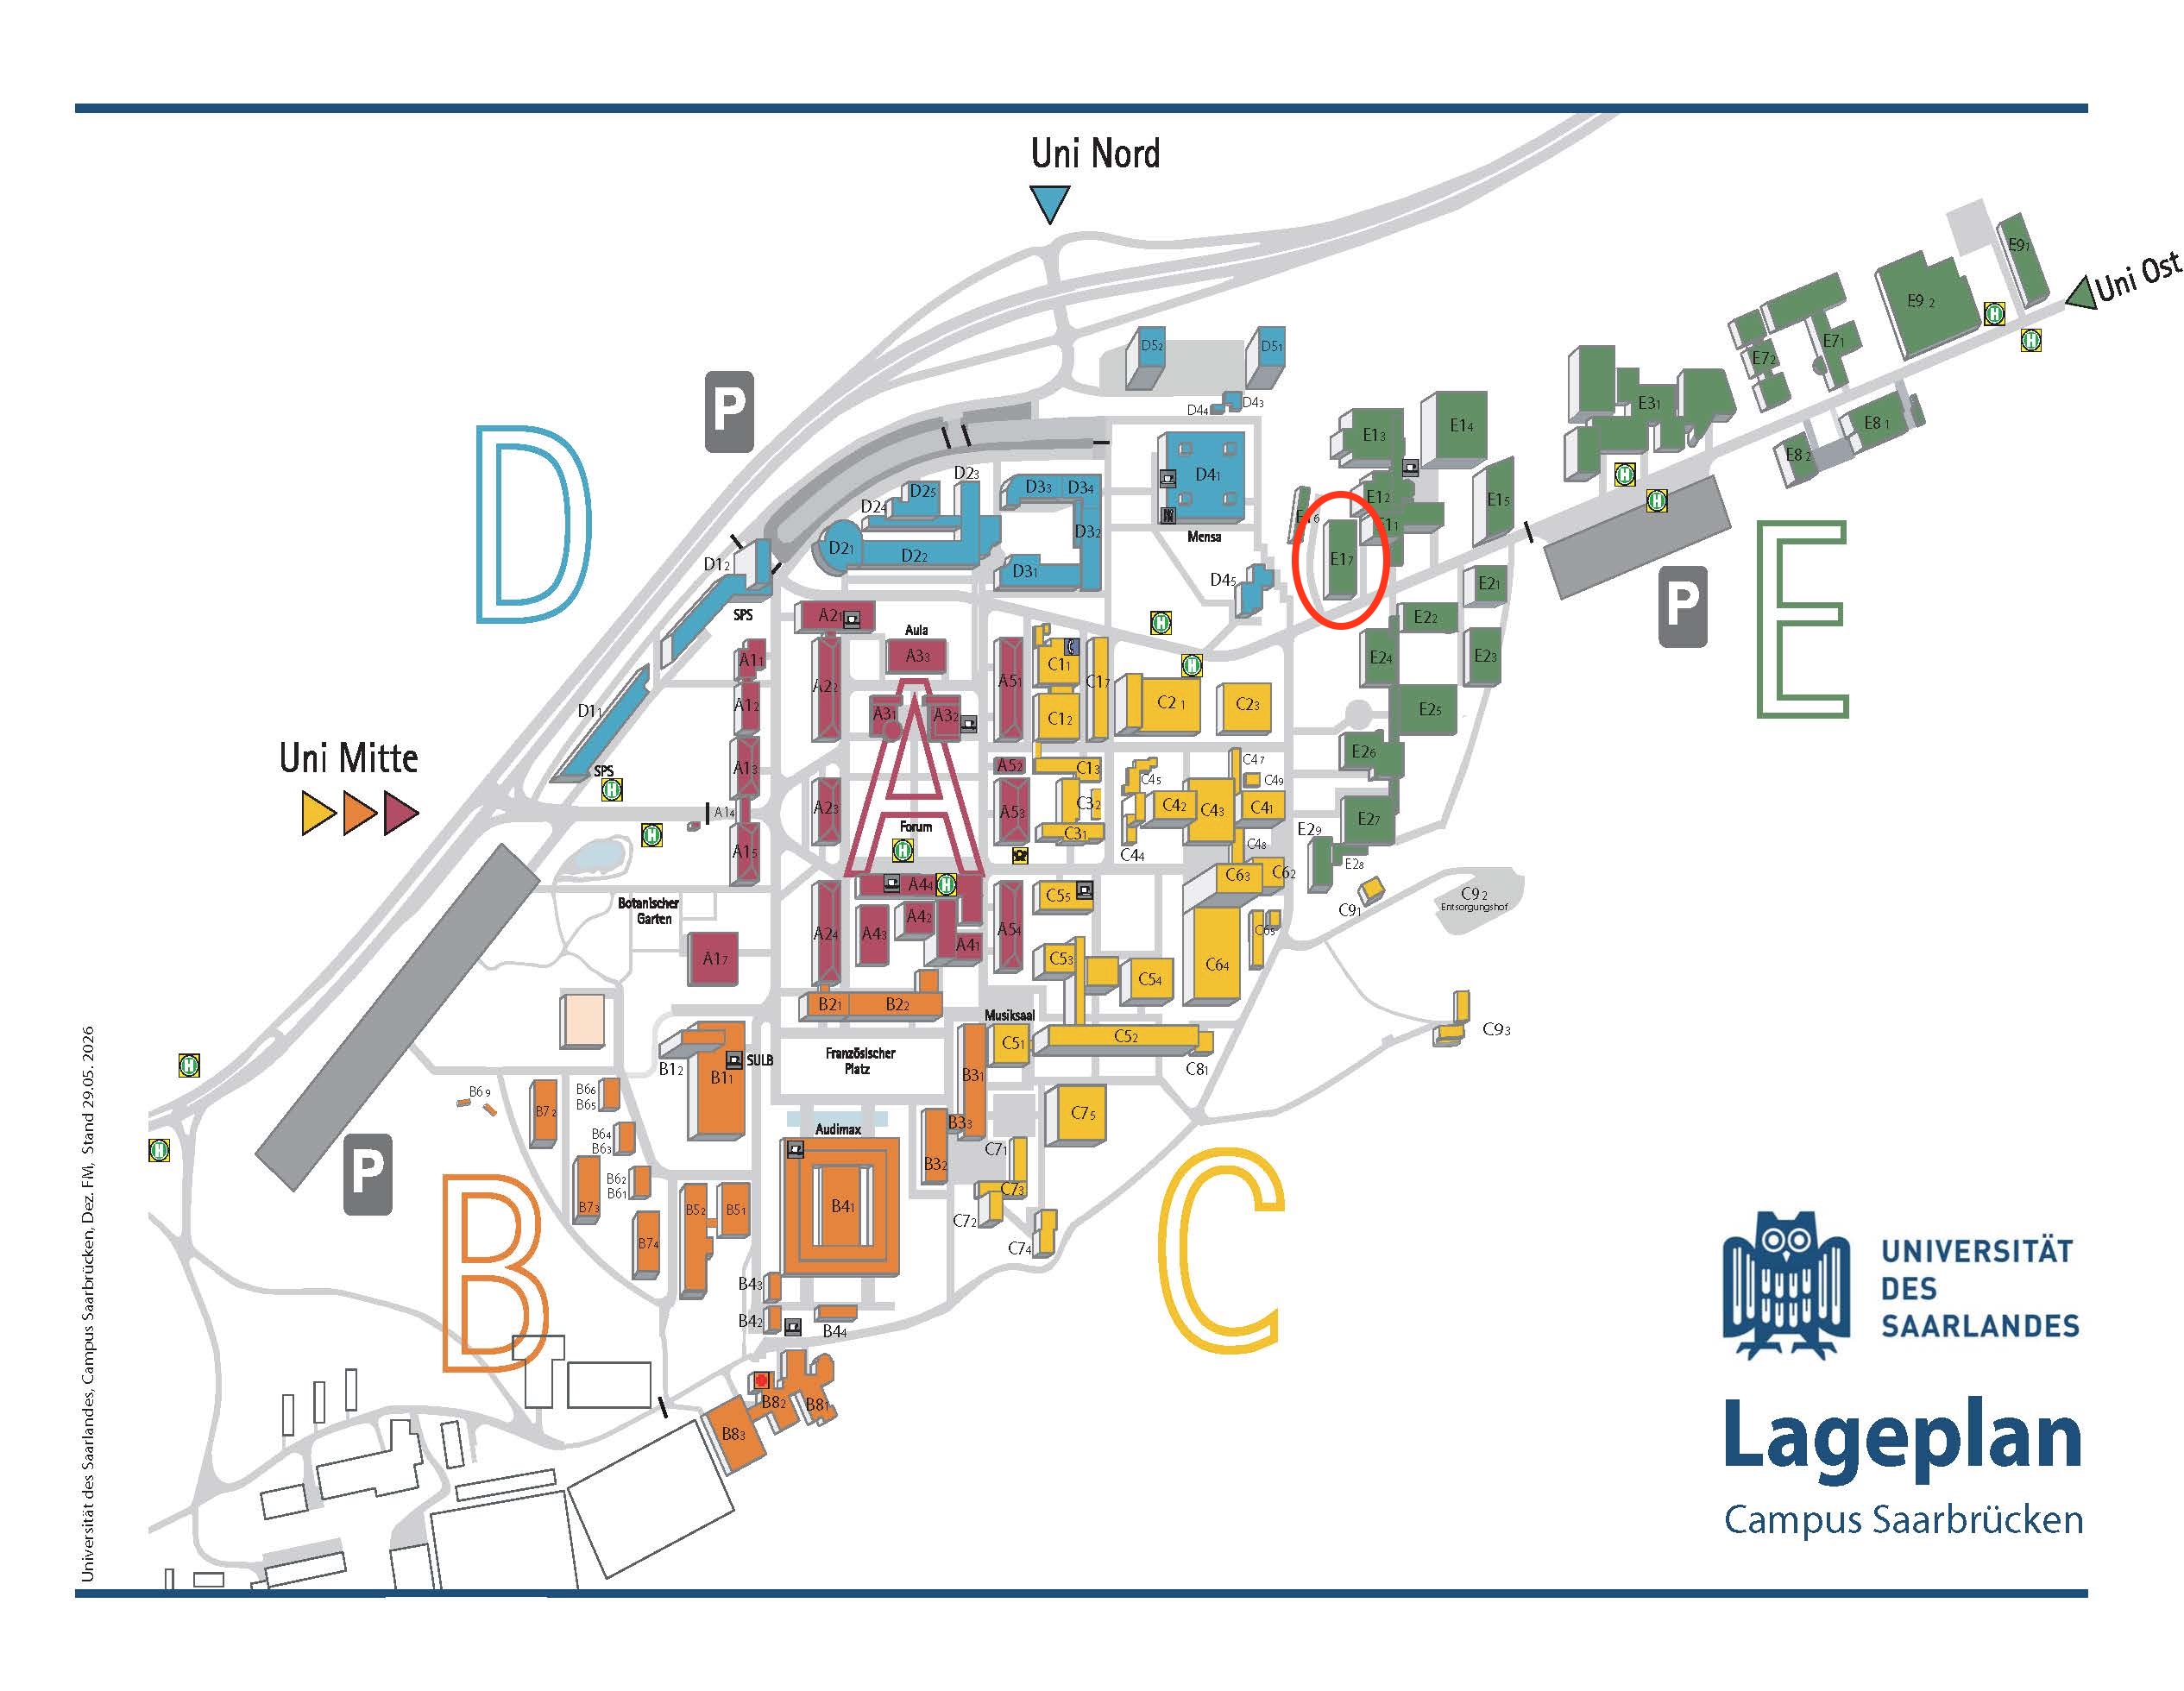
Wo? Campus Saarbrücken, Gebäude E1.7, Raum 3.23
Anfahrt:
- Mit Bus: Haltestelle “Universität Mensa, Saarbrücken” - Linien 101, 102, 109, 111, 112, 124, 136, 138, 150, 163, 170, 320, 817, 819, 821, 834
- Mit Auto:
- Aus Richtung Dudweiler: Dudweilerstraße L251, Einfahrt Uni Ost, Parkhaus Uni Ost
- Aus Richtung Saarbrücken Innenstadt: Stuhlsatzenhausenweg L252, Einfahrt Uni Mitte, Parkhaus Uni Mitte

Sie haben Fragen zur Ringvorlesung?
Dr. Martin Ulrich
Referent Graduatierenkolleg / Zertifikat SOUNDS
Campus Saarbrücken
Geb. E 1 1, 4.06.3
Tel.: +49 681 302-70784
martin.ulrich(at)uni-saarland.de